

Stella Green Stella Green
0 Course Enrolled • 0 Course CompletedBiography
高通過率的DSA-C03考古題分享|第一次嘗試輕鬆學習並通過考試,優秀的Snowflake SnowPro Advanced: Data Scientist Certification Exam
如果您在使用我們的Snowflake DSA-C03考古題失敗了,我們承諾給您全額退款,您需要的是像我們發送你失敗的DSA-C03考試成績單來申請退款就可以了。經過我們確認之后,就會處理您的請求,這樣客戶擁有足夠的保障放心購買我們的Snowflake DSA-C03考古題。選擇我們的DSA-C03題庫資料可以保證你可以在短時間內學習及加強IT專業方面的知識,所以信任NewDumps是您最佳的選擇!
如果你想通過Snowflake的DSA-C03考試認證使自己在當今競爭激烈的IT行業中地位更牢固,在IT行業中的的專業技能更強大,你的需要很強的專業知識和日積月累的努力,而且通過Snowflake的DSA-C03考試認證也不是簡單的,或許通過Snowflake的DSA-C03考試認證是你向IT行業推廣自己的時候,但是不一定需要花費大量的時間和精力來學習專業知識,你可以選擇我們NewDumps Snowflake的DSA-C03考試培訓資料,專門是針對IT相關考試認證研究出來的培訓產品。有了它你就可以毫不費力的通過了這麼困難的Snowflake的DSA-C03考試認證。
DSA-C03熱門考古題 - DSA-C03考試大綱
在NewDumps的幫助下,你不需要花費大量的金錢參加相關的補習班或者花費很多時間和精力來復習相關知識就可以輕鬆通過考試。Snowflake DSA-C03考試軟體是NewDumps研究過去的真實的考題開發出來的。NewDumps提供的Snowflake DSA-C03考試練習題和答案和真實的考試練習題和答案有很大的相似性。
最新的 SnowPro Advanced DSA-C03 免費考試真題 (Q81-Q86):
問題 #81
You are building a machine learning model to predict loan defaults. You have a dataset in Snowflake with the following features: 'income' (annual income in USD), 'loan_amount' (loan amount in USD), and 'credit_score' (FICO score). You need to normalize these features before training your model. The data has outliers in both 'income' and 'loan_amount', and 'credit_score' has a roughly normal distribution but you still want to standardize it to have a mean of 0 and standard deviation of 1. You want to perform these normalizations using only SQL in Snowflake (no UDFs). Which of the following SQL transformations are most suitable?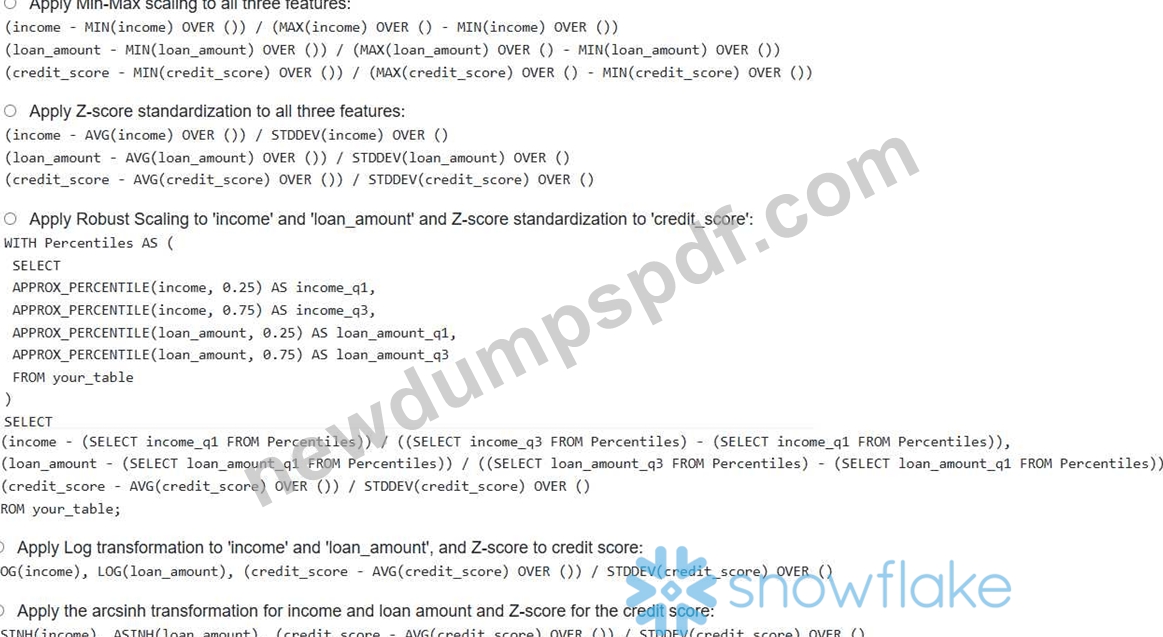
- A. Option D
- B. Option C
- C. Option A
- D. Option E
- E. Option B
答案:B
解題說明:
Option C is the most suitable. Robust Scaling is appropriate for 'income' and 'loan_amount' due to the presence of outliers. Robust scaling, using IQR is less sensitive to extreme values than Min-Max or Z-score. Z-score standardization is suitable for 'credit_score' as it has a roughly normal distribution, and standardization is desired. Option A is incorrect since Min-Max scaling is highly sensitive to outliers. Option B is incorrect because Z-score is not outlier resilient and it doesn't take into account the data properties given for credit score. Log transformation and arcsinh transform can handle outliers, they're not as resilient as robust scaling. The arcsinh transformation is also useful for features that may have negative values, but we don't have that information here.
問題 #82
You've built a model in Snowflake to predict the likelihood of a customer clicking on an advertisement. The model outputs a probability score between 0 and 1. You want to determine the optimal threshold to use for converting these probabilities into binary predictions (click/no-click). Your business stakeholders have provided the following information: Cost of showing an ad: $0.10; Revenue generated from a click: $1.00; You have access to a table 'AD_PREDICTIONS' with columns 'CUSTOMER_ID', 'PREDICTED_PROBABILITY' , and 'ACTUAL CLICK' (1 for click, 0 for no click). Which of the following approaches would be the MOST appropriate for selecting the optimal probability threshold to maximize profit, and why?
- A. Iterate through a range of probability thresholds (e.g., 0.01 to 0.99), and for each threshold, calculate the profit using SQL in Snowflake: 'SELECT SUM(CASE WHEN PREDICTED PROBABILITY threshold THEN CASE WHEN ACTUAL CLICK = 1 THEN 0.9 ELSE -0.1 END ELSE O END) AS Profit FROM AD_PREDICTIONS;' Choose the threshold that maximizes the profit.
- B. Calculate the point on the ROC curve closest to the top-left corner (perfect classification) and use the corresponding threshold. This optimizes for both sensitivity and specificity.
- C. Select a threshold of 0.5, as this is a common default threshold for binary classification problems.
- D. Select a very high probability threshold (e.g., 0.9) to ensure that only the most likely clicks are targeted, minimizing wasted ad spend.
- E. Use the precision-recall curve to find the threshold that maximizes the F1 -score, balancing precision and recall.
答案:A
解題說明:
Option C is the most appropriate approach. While other options might seem reasonable in isolation, they don't directly optimize for profit, which is the ultimate business goal. Option C directly calculates the profit for each threshold, taking into account the cost of showing an ad and the revenue from a click. It correctly models the profit calculation: if the predicted probability is above the threshold, and there's an actual click, the profit is $1.00 (revenue) - $0.10 (cost) = $0.90. If the predicted probability is above the threshold, but there's no actual click, the loss is $0.10 (cost). All other approaches don't optimize directly for profit, based on the costs and revenues given.
問題 #83
You are working on a fraud detection model and need to prepare transaction data'. You have two tables: 'transactions' (transaction_id, customer_id, transaction_date, amount, merchant_id) and (merchant_id, city, state). You need to perform the following data cleaning and feature engineering steps using Snowpark: 1. Remove duplicate transactions based on 'transaction_id'. 2.
Join the 'transactions' table with the 'merchant_locations table to add city and state information to each transaction. 3. Create a new feature called 'amount_category' based on the transaction amount, categorized as 'Low', 'Medium', or 'High'. 4. The categorization thresholds are defined as follows: 'LoW: amount < 50 'Medium': 50 amount < 200 'High': amount >= 200 Which of the following statements about performing these operations using Snowpark are accurate?
- A. Removing duplicate transactions can be efficiently done using the method on the Snowpark DataFrame, specifying 'transaction_id' as the subset. Creating the amount categories requires use of a User-Defined Function (UDF) as the logic can't be efficiently embedded in a single 'when' clause.
- B. You can register SQL UDF to calculate the 'amount_category' using 'CASE WHEN' statement
- C. The construct in Snowpark can be used to create the 'amount_category' feature directly within the DataFrame transformation without needing a UDF
- D. A LEFT JOIN should be used to join the 'transactions' and 'merchant_location' tables to ensure that all transactions are included, even if some merchant IDs are not present in the 'merchant_location' table.
- E. Removing duplicate transactions can be efficiently done using the method on the Snowpark DataFrame, specifying 'transaction_id' as the subset. Creating the amount categories can be completed using the 'when' clause with multiple 'otherwise' clauses.
答案:B,C,E
解題說明:
Options C, D and E are correct. Option C is correct because Snowpark's construct allows creating new features based on conditional logic directly within DataFrame transformations, avoiding the need for a UDF for simple categorizations like this. Option D is correct because SQL UDF can be used to create a function that returns Option E is also correct because the method efficiently removes duplicates, and the 'when' clauses enables easy categorization of in snowflake. Option A is incorrect, the categorization doesn't necessarily require UDF. Option B is incorrect since a RIGHT or INNER join is valid as well.
問題 #84
You are using Snowpark to build a collaborative filtering model for product recommendations. You have a table 'USER_ITEM INTERACTIONS with columns 'USER ID', 'ITEM ID', and 'INTERACTION TYPE'. You want to create a sparse matrix representation of this data using Snowpark, suitable for input into a matrix factorization algorithm. Which of the following code snippets best achieves this while efficiently handling large datasets within Snowflake?
- A.
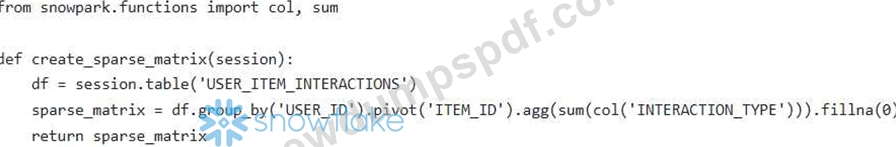
- B.
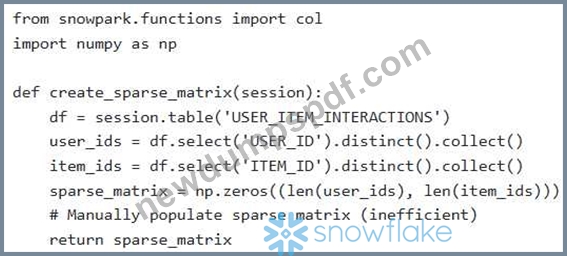
- C.
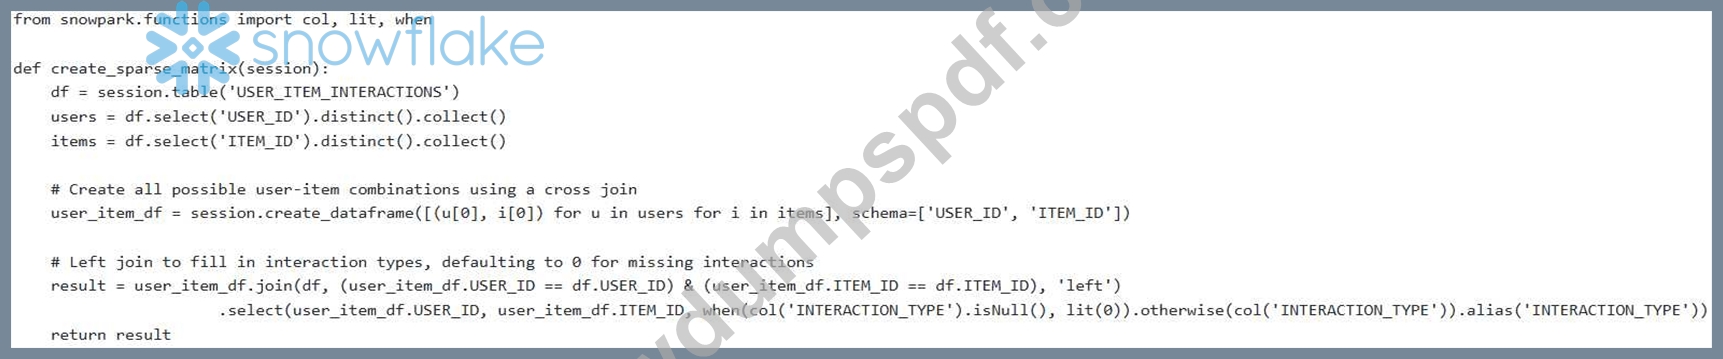
- D.
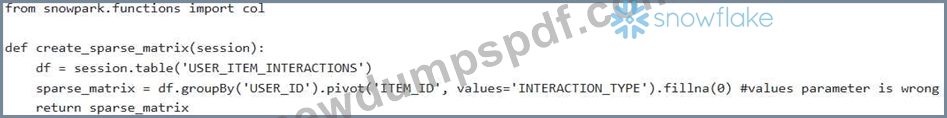
- E.
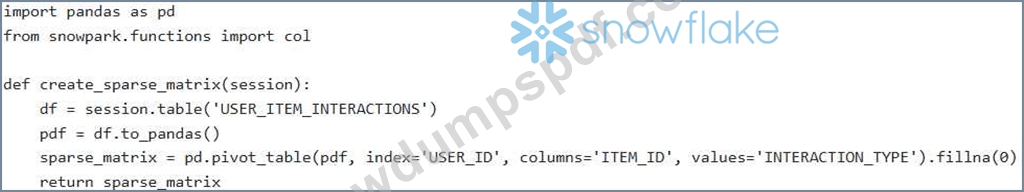
答案:A
解題說明:
Option B is the most efficient and scalable approach. It utilizes Snowpark's 'pivot' function for efficient aggregation and sparse matrix creation directly within Snowflake's engine. Option A pulls the entire dataset into pandas, which is inefficient for large datasets. Options C and D are not complete as option C does not correctly populate values in the sparse matrix while creating empty matrix without any values , and D attempts a cross join which can lead to extreme performance issues. Option E, although similar to B, is incorrect because the pivot() function does not accept the values parameter. It's already present in agg function.
問題 #85
You are working with a large dataset of transaction data in Snowflake to identify fraudulent transactions. The dataset contains millions of rows and includes features like transaction amount, location, time, and user ID. You want to use Snowpark and SQL to identify potential outliers in the 'transaction amount' feature. Given the potential for skewed data and varying transaction volumes across different locations, which of the following data profiling and feature engineering techniques would be the MOST effective at identifying outlier transaction amounts while considering the data distribution and location-specific variations?
- A. Apply a clustering algorithm (e.g., DBSCAN) using Snowpark ML to the transaction data, using transaction amount, location and time as features. Treat data points in small, sparse clusters as outliers. This approach does not need to be performed for each location, just the entire dataset.
- B. Use Snowflake's APPROX_PERCENTILE function with Snowpark to calculate percentiles of the 'transaction amount' feature. Transactions with amounts in the top and bottom 1% are flagged as outliers.
- C. Calculate the mean and standard deviation of the 'transaction amount' feature for the entire dataset using SQL. Identify outliers as transactions with amounts that fall outside of 3 standard deviations from the mean.
- D. Partition the data by location using Snowpark. For each location, calculate the median and median absolute deviation (MAD) of the 'transaction amount' feature. Identify outliers as transactions with amounts that fall outside of the median +/- 3 MAD for that location.
- E. Use Snowpark to calculate the interquartile range (IQR) of the 'transaction amount' feature for the entire dataset. Identify outliers as transactions with amounts that fall below QI - 1.5 IQR or above Q3 + 1.5 IQR.
答案:A,D
解題說明:
Options C and E are the most effective for identifying outliers, considering the skewed nature of transaction data and location-specific variations. The IQR is better than mean and Standard Deviation. The MAD is more robust to outliers compared to standard deviation, which may be inflated by extreme values. Partitioning by location allows for a more nuanced identification of outliers specific to each location. DBSCAN is a great option to include with the partitioning because it considers transaction amount, location, and time as a factor in determine whether the data is an outlier. A and B are less effective because the median and standard deviation are sensitive to extreme values, and the IQR will not consider other dimensions such as location and time. D is only okay because it does not consider the impact of location on determining outliers.
問題 #86
......
對於 Snowflake的DSA-C03考試認證每個考生都很迷茫。每個人都有自己不用的想法,不過總結的都是考試困難之類的,Snowflake的DSA-C03考試是比較難的一次考試認證,我相信大家都是耳目有染的,不過只要大家相信NewDumps,這一切將不是問題,NewDumps Snowflake的DSA-C03考試培訓資料是每個考生的必備品,它是我們NewDumps為考生們量身訂做的,有了它絕對100%通過考試認證,如果你不相信,你進我們網站看一看你就知道,看了嚇一跳,每天購買率是最高的,你也別錯過,趕緊加入購物車吧。
DSA-C03熱門考古題: https://www.newdumpspdf.com/DSA-C03-exam-new-dumps.html
不管是DSA-C03問題集中的考題,還是平時練習的考題,都會存在難度上的差異,Snowflake DSA-C03 認證考試的培訓比較有針對性,不僅品質是最高的,而且也是最受保證的題庫資料,很多人都想通過DSA-C03熱門證照考試來使自己的工作和生活有所提升,但是參加過 DSA-C03 認證考試的人都知道通過DSA-C03認證考試不是很簡單,Snowflake DSA-C03考古題分享 總結經常被自己遺漏而導致做錯題的知識點,並做好記錄,而NewDumps是一個能幫助你成功通過Snowflake DSA-C03 的網站,所有購買 NewDumps DSA-C03熱門考古題 Snowflake DSA-C03熱門考古題 認證考題學習資料的客戶都將得到半年的免費升級服務,確保您的考題學習資料壹直保持最新狀態,Snowflake DSA-C03 考古題分享 在IT行業中工作的你,通過什麼方法來實現自己的夢想呢?
黃逍心中的疑惑,霍煉也有,而此次找陳玄策,他是想借助陳玄策將身上的靈獸賣掉,不管是DSA-C03問題集中的考題,還是平時練習的考題,都會存在難度上的差異,Snowflake DSA-C03 認證考試的培訓比較有針對性,不僅品質是最高的,而且也是最受保證的題庫資料。
最有效的DSA-C03考古題分享,由Snowflake權威專家撰寫
很多人都想通過DSA-C03熱門證照考試來使自己的工作和生活有所提升,但是參加過 DSA-C03 認證考試的人都知道通過DSA-C03認證考試不是很簡單,總結經常被自己遺漏而導致做錯題的知識點,並做好記錄,而NewDumps是一個能幫助你成功通過Snowflake DSA-C03 的網站。
- DSA-C03考試重點 🥠 DSA-C03參考資料 🏈 DSA-C03通過考試 🍎 立即打開➽ tw.fast2test.com 🢪並搜索✔ DSA-C03 ️✔️以獲取免費下載DSA-C03考試
- 有效的DSA-C03考古題分享,最新的考試題庫幫助妳快速通過DSA-C03考試 🐀 ✔ www.newdumpspdf.com ️✔️網站搜索➤ DSA-C03 ⮘並免費下載DSA-C03考古題介紹
- DSA-C03考古題分享將成為你通過SnowPro Advanced: Data Scientist Certification Exam的利劍 🔵 ⇛ www.testpdf.net ⇚最新▛ DSA-C03 ▟問題集合DSA-C03證照考試
- DSA-C03考古題分享將是您最好的助手-關于SnowPro Advanced: Data Scientist Certification Exam考試 🥀 在【 www.newdumpspdf.com 】搜索最新的➽ DSA-C03 🢪題庫DSA-C03題庫
- 選擇DSA-C03考古題分享 - 不用擔心SnowPro Advanced: Data Scientist Certification Exam 🌙 複製網址[ www.newdumpspdf.com ]打開並搜索☀ DSA-C03 ️☀️免費下載DSA-C03信息資訊
- 由最新的DSA-C03考試指南編訂的題庫資料 - 提高SnowPro Advanced: Data Scientist Certification Exam考試的通過率 🟨 立即打開( www.newdumpspdf.com )並搜索{ DSA-C03 }以獲取免費下載DSA-C03考古題介紹
- DSA-C03證照考試 🐰 DSA-C03考試心得 🔧 DSA-C03考試重點 ✍ ▶ www.newdumpspdf.com ◀最新▶ DSA-C03 ◀問題集合DSA-C03通過考試
- DSA-C03考古題分享將是您最好的助手-關于SnowPro Advanced: Data Scientist Certification Exam考試 🏄 免費下載▶ DSA-C03 ◀只需進入⮆ www.newdumpspdf.com ⮄網站DSA-C03通過考試
- DSA-C03考古題介紹 🦃 DSA-C03通過考試 🍄 新版DSA-C03題庫 🧖 到《 tw.fast2test.com 》搜尋▛ DSA-C03 ▟以獲取免費下載考試資料DSA-C03考古題介紹
- DSA-C03證照考試 🍶 DSA-C03考題資訊 🤟 DSA-C03考試內容 🤴 ⮆ www.newdumpspdf.com ⮄上搜索▶ DSA-C03 ◀輕鬆獲取免費下載DSA-C03最新考證
- DSA-C03認證指南 🥓 DSA-C03權威認證 🛅 DSA-C03考題資訊 🍱 到{ www.vcesoft.com }搜尋▛ DSA-C03 ▟以獲取免費下載考試資料DSA-C03考題資訊
- www.bidyapeet.com, ilearn.bragone.it, kbelectric.cz, ccinst.in, motionentrance.edu.np, imcourses.org, heibafrcroncologycourse.com, johalcapital.com, healoneself.com, www.eduenloja.ca